AI features your users trust, because you can show they work.
Search over your own documents, assistants that take real actions, extraction that replaces manual data entry. Built with evaluations from the first week, so quality is a number rather than a hope.
- Evaluated, not guessed
- Grounded in your data
- Costs you can predict
When AI belongs in your product, and when it doesn't.
The projects that pay for themselves are narrow ones aimed at real work. These are the situations where AI usually earns its keep.
- 01
Answers are buried in documents
Policies, manuals and past tickets hold the answer, but people can't find it quickly.
- 02
Customers ask the same things
Support repeats itself, and a grounded assistant could answer most of it with sources.
- 03
People re-type documents
Invoices, forms and IDs are read and keyed in by hand, slowly and with errors.
- 04
Your competitors shipped an AI feature
You need one that actually works, not a chatbot bolted into the corner.
- 05
An AI demo won't hold up
A prototype impressed in a meeting but fails on real data, and nobody can measure it.
- 06
AI costs are unpredictable
Usage is growing and so is the bill, with no clear view of cost per request.
Add AI to what you have, or build around it.
Almost everyone should start with the first. The second is a real strategy, but only when the model is genuinely the product.
| Consideration | AI inside your product | AI-native product |
|---|---|---|
| Right for | AI inside your productAlmost every team | AI-native productWhen the intelligence is what you sell |
| Starts with | AI inside your productOne expensive workflow | AI-native productData pipeline and retrieval design |
| Models | AI inside your productFrontier model APIs, no training | AI-native productFine-tuned or smaller models where economics demand |
| Evaluation | AI inside your productA test set for that feature | AI-native productAn evaluation harness as core infrastructure |
| Risk | AI inside your productLow, a person stays in the loop | AI-native productHigher, the interface must handle being wrong |
We'll tell you honestly if AI is the wrong tool. Sometimes the right answer is a better form or a database query.
AI that does a specific job, not a chatbot in the corner.
Each of these is narrow on purpose. Narrow problems can be measured, and measured problems can be trusted.
- 01
RAG and semantic search
Ask questions of your own documents, policies or tickets and get answers grounded in sources, with citations to check.
- Document search
- Citations
- Hybrid search
- 02
Assistants and copilots
In-product help that can actually do things: draft, summarise, look up and take actions against your API.
- Drafting
- Summaries
- Tool use
- 03
Document extraction
Invoices, KYC documents, contracts and forms turned into structured data, with confidence scores and human review where it matters.
- Invoices
- KYC
- Contracts
- 04
Classification and routing
Tickets, leads and messages sorted, tagged and sent to the right place. The least glamorous, most reliable win.
- Tickets
- Leads
- Intent
- 05
AI-native features
Recommendations, generation and smart defaults designed into the product, with fallbacks for when the model is unsure.
- Recommendations
- Generation
- Smart defaults
- 06
Evaluation and monitoring
Test sets, scoring and dashboards for AI you already run, so you can change a prompt without crossing your fingers.
- Golden sets
- Regression tests
- Cost tracking
From an idea about AI to a feature that holds up in production.
The evaluation set comes before the tuning, so every change after it is measured instead of judged by feel.
- 01
Find the expensive task
We look for repetitive judgement work with a clear right answer. Best returns, least risk.
You get- Use-case brief
- 02
Prove feasibility
A spike against your real data in days, so we learn early whether this is achievable at all.
You get- Feasibility spike
- Go or no-go
- 03
Build the eval set
Real examples, expected answers and an agreed bar for good enough, before anything is tuned.
You get- Evaluation set
- Quality bar
- 04
Build the feature
Retrieval, prompts, tools and interface together, designed for a system that's occasionally wrong.
You get- Working feature
- Eval scores
- 05
Harden
Adversarial testing, cost and latency tuning, fallbacks and the path to a person when it matters.
You get- Cost per request
- Fallbacks
- 06
Ship and watch
A staged rollout with monitoring and feedback capture, then improvement against what real use shows.
You get- Monitoring
- Feedback loop
What we build is yours. In writing.
Software you'll run for years shouldn't tie you to the people who wrote it. Once the work is paid for it's yours outright, handed over in accounts you control.
- 01
Code and IP
Full ownership of the code and design files passes to you on payment. No licence fees, ever.
- 02
Your own accounts
Repositories, hosting, stores and domains are handed over in your name, not kept in ours.
- 03
Documentation
Setup guides, architecture notes and a record of key decisions, so any capable team can pick it up.
- 04
Confidentiality
We sign an NDA before you share anything sensitive, and treat your data that way throughout.
The engineering that turns a demo into something you can sell.
Anyone can get a convincing result once. The work is making it right often enough, cheaply enough, and knowing which it was.
- Quality
An evaluation set
Real examples with known-good answers, scored on every change, so quality is measurable.
- Grounding
Answers with sources
Responses tied to your content with citations, which is how you cut confident nonsense.
- Safety
Graceful failure
It says when it doesn't know and hands over to a person, rather than inventing an answer.
- Cost
Cost controls
Token budgets, caching and model routing, so a spike in usage isn't a spike in your bill.
- Privacy
Data protection
Personal data redaction, retention rules and no training on your data, aligned with the DPDP Act.
- Security
Prompt-injection defence
Untrusted input treated as data, tool permissions scoped tightly, actions confirmed.
Model-agnostic, so you're never trapped by one vendor.
We keep the model behind an interface. When something cheaper or better arrives, and it does constantly, switching is a configuration change.
Models
- Claude
- OpenAI
- Gemini
- Open-weight models
Retrieval
- pgvector
- Qdrant
- Hybrid search
- Rerankers
Orchestration
- Tool use
- Structured output
- MCP
- Streaming
Evaluation
- Golden sets
- LLM-as-judge
- Langfuse
Application
- TypeScript
- Python
- Next.js
- FastAPI
Start where you are, with a fixed quote first.
Every engagement starts with an itemised proposal. Pick the model that fits what you already know.
- 01Discovery sprintThe problem is clear, the solution isn't yet
- 02Fixed-scope buildRequirements are understood and agreed
- 03Dedicated product teamThe product is live and keeps growing
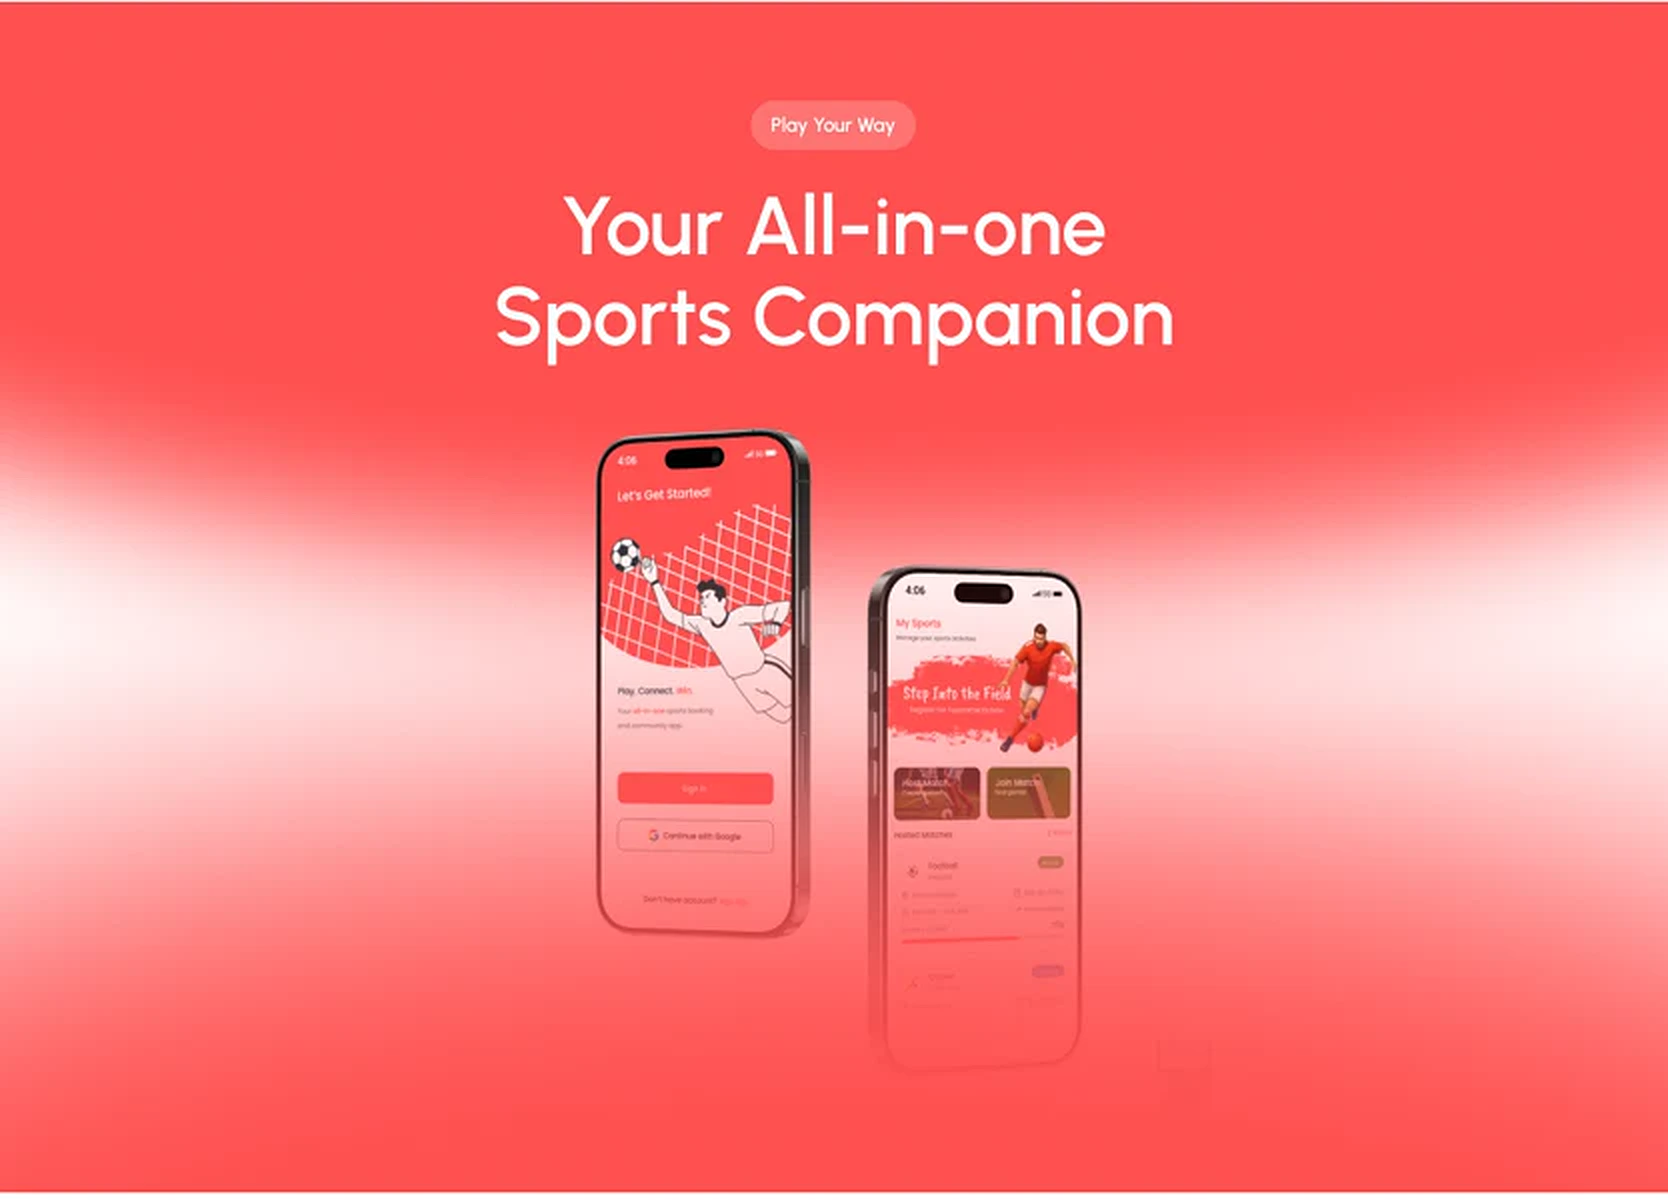
Recent work from the studio.
A look at what we've designed, built and launched recently.
Is it really an AI feature?
If the job is automating your own operations, or building the product around the feature, start with one of these.
- AI Automation & AgentsYou want agents to run internal workflows like invoices, tickets or CRM updates.
- SaaS Product DevelopmentThe AI feature lives inside a SaaS product that needs its foundations too.
- Custom Software DevelopmentAI is one part of a bigger internal system.
- MVP DevelopmentYou're testing whether an AI product idea works at all.
- UI/UX Product DesignThe hard part is designing an interface people trust with AI.
- Ongoing Product EngineeringYour AI features are live and need monitoring and steady improvement.
Questions
The things people
ask us first.
If yours isn’t here, send it over. We reply within 1 hour, guaranteed, and you’ll get a straight answer rather than a brochure.
Do we need to train our own model?
+
Almost certainly not. For most business problems, a frontier model with good retrieval over your own data beats a fine-tuned small model and costs a fraction to build and maintain. Fine-tuning is worth it for narrow, high-volume tasks where cost per request or speed is the binding constraint.
What is RAG, in plain terms?
+
Retrieval-augmented generation. Rather than hoping a model memorised your information, you search your own documents for the relevant passages and give them to the model with the question. Answers stay current, stay grounded in your content, and can cite where they came from.
How do you stop it making things up?
+
Several layers: answers grounded in retrieved sources with citations, prompts where 'I don't know' is acceptable, constrained output formats, and an evaluation set that includes questions the system should refuse. You reduce it to a rate you measure and manage.
Is our data safe, and will it be used for training?
+
We use enterprise API tiers where inputs aren't used to train the providers' models, redact personal data before it leaves your systems where the use case allows, and set retention rules deliberately. For sensitive workloads we can run open-weight models in your own cloud.
How much does it cost to run?
+
Running cost is per request, and it's manageable once measured. We track token usage from the start and use caching, prompt design and cheaper models for easier requests. You'll have a cost-per-request figure before anything goes live.
What if the model changes or gets deprecated?
+
We keep model access behind an internal interface and maintain an evaluation set, so switching providers means changing configuration and re-running the evals.


Where ambitious
ideas become reality.
We design, develop, and support digital experiences that turn ambitious ideas into meaningful products.